Linguistic Clustering
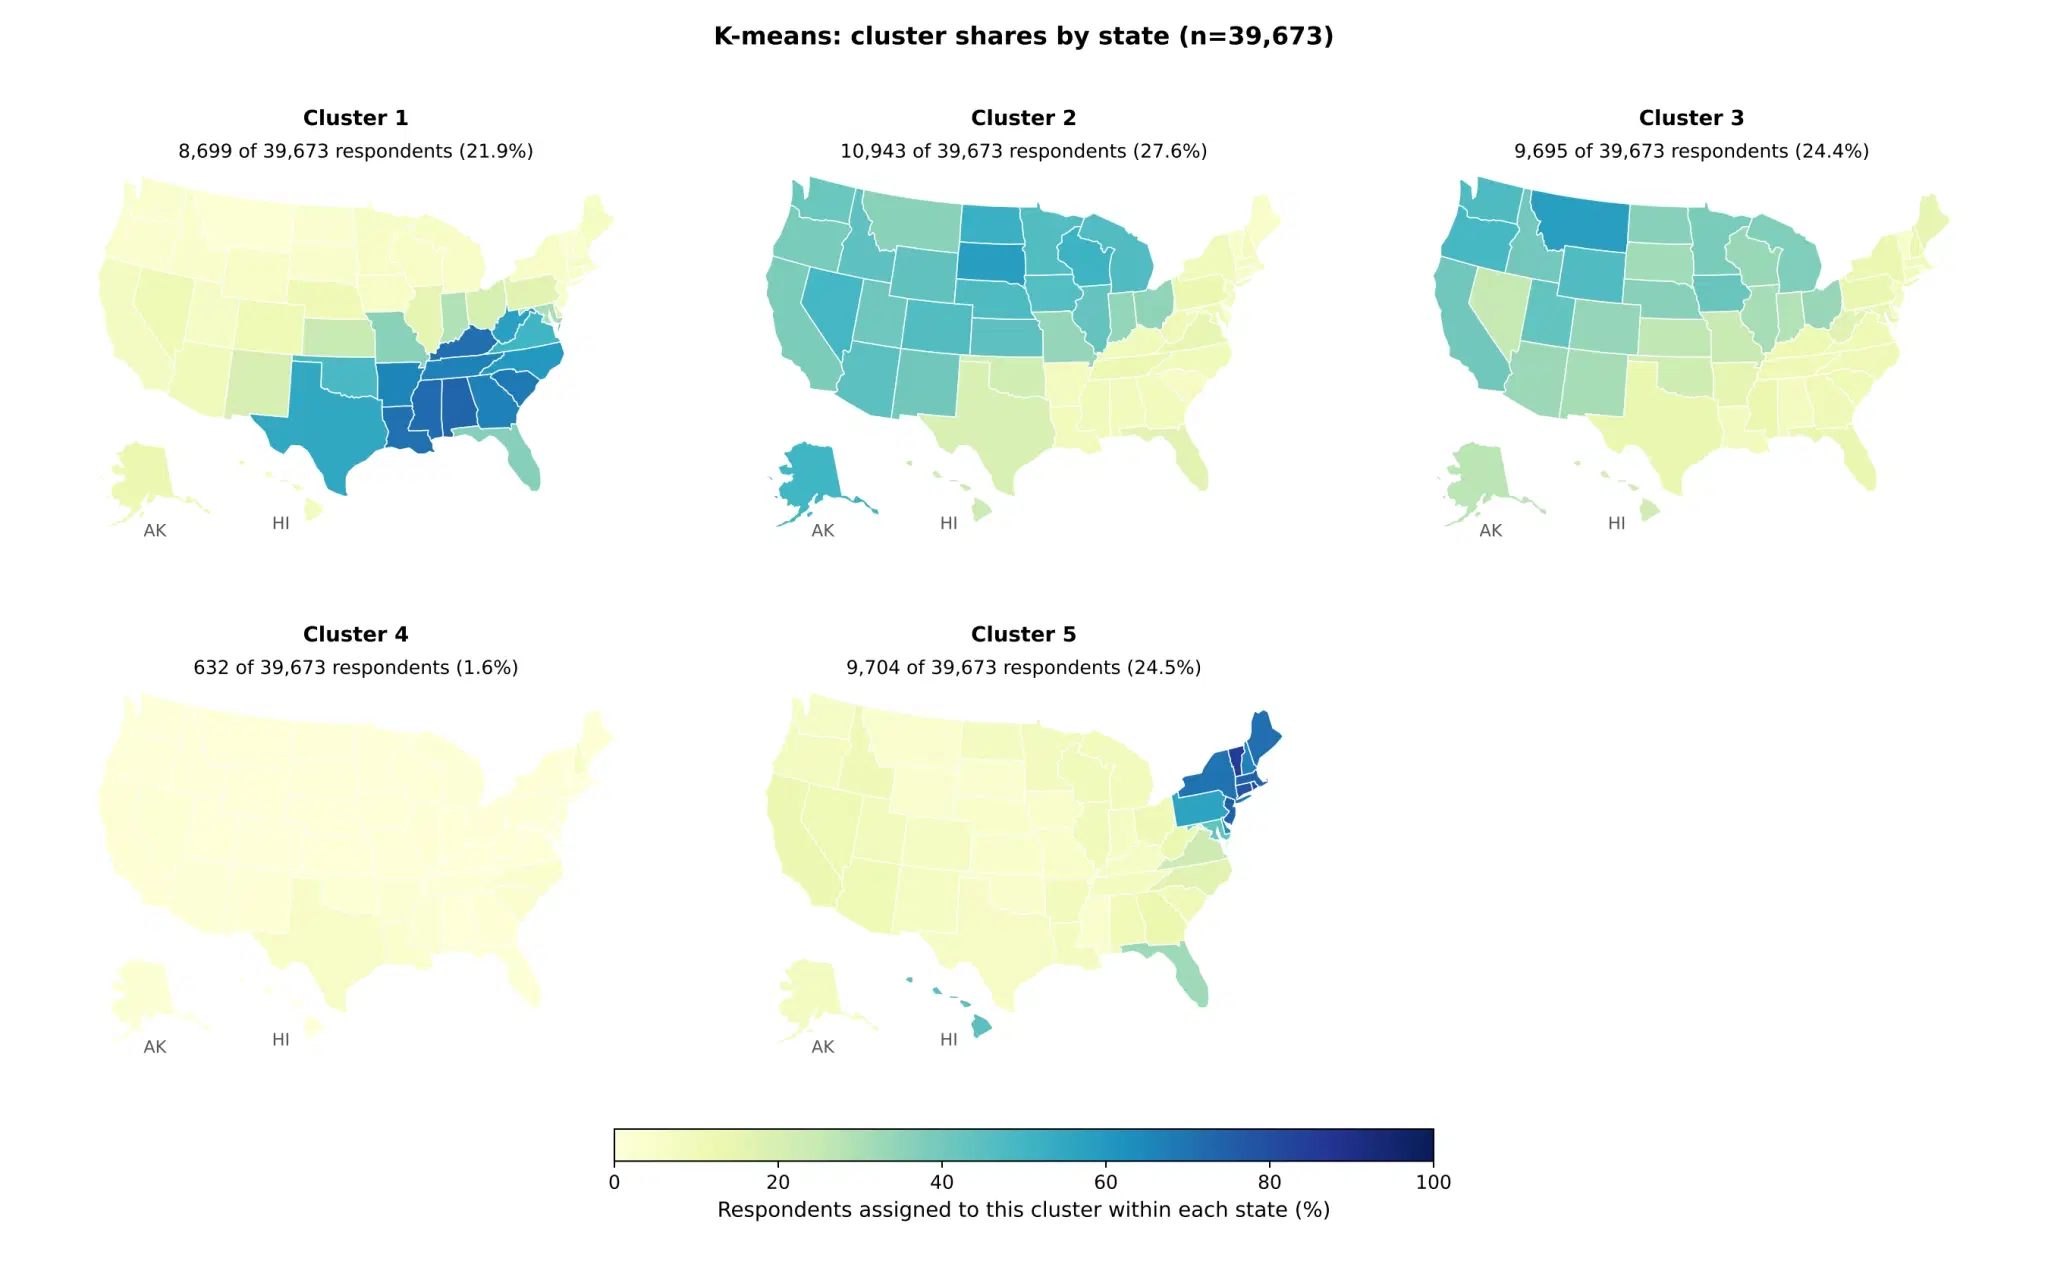
For this project, I explored regional patterns in how people use different words, using a survey of 47,471 respondents. I cleaned the data, encoded responses as 468 binary features, and compared PCA and t-SNE before fitting K-means and Gaussian mixture models.
I then checked whether the clusters stayed similar across different starting points and bootstrap samples. Some broad regional patterns repeated, while the less stable groups showed why clusters should not automatically be treated as separate dialects.
This project was created as Lab 2 in the course "Applied Statistics and Machine Learning" (STAT 215A) at UC Berkeley in fall 2026.
If you want to learn more about the analysis, you can find the report here. You can also download the code here.
Below is a visualization of the K-means clusters across U.S. states.